
Three Different Views of the Same Underlying Problem
Blocking Chains shows what’s blocked right now. These 3 scripts go wider and deeper: Get-LockEscalationStats finds which tables have converted row/page locks into full table locks (a common, self-inflicted cause of blocking), Get-ContentionAnalysis rolls up lock waits, latch waits, page latch waits and spinlock collisions into one summary since the last restart, and Get-BlockingChainsWithPlan is Blocking Chains with the actual execution plan attached for every blocked or blocking session, so you can see not just who’s blocked but what query is doing it.
Together they cover 3 different angles on the same underlying question: is locking or latching actually costing this server anything, and if so, where. If something is blocked right now and you want the order of work rather than the scripts, start at Troubleshoot SQL Server Blocking, Step by Step and come back here for the detail.
Why Lock Escalation, Contention, and Blocking Plans Matter
- Lock escalation converts many fine-grained row/page locks into one table lock, which can block readers and writers that would have coexisted fine under row-level locking, a frequent, avoidable blocking cause
- Cumulative wait statistics (lock, latch, TempDB, spinlock) since the last restart tell you where contention has actually cost time, not just where it’s theoretically possible
- A blocking chain with the query plan attached turns “session 62 is blocking session 78” into “this specific query, with this specific plan, is the actual problem,” the difference between guessing and fixing
- SQL Server Cannot Obtain a LOCK Resource at This Time (Error 1204), where lock escalation being switched off turns into this exact error
- Page latch waits (
PAGELATCH_UPandPAGELATCH_EX) have a well-known direct fix when they land on TempDB allocation pages, adding TempDB data files, and no fix at all when they land somewhere else, which is why the database has to be confirmed before the change
When to Run These Scripts
- Get-LockEscalationStats, when investigating blocking that seems disproportionate to the actual data touched, escalation is a common hidden cause
- Get-ContentionAnalysis, as a general health check or when investigating a vague “performance feels off” report, it surfaces contention across 4 different resource types in one pass
- Get-BlockingChainsWithPlan, during an active blocking incident, when Get-BlockingChains has identified the sessions involved and you need the actual query and plan to fix the root cause
- Routine SQL Server health checks, alongside the rest of the Blocking and Locking cluster
The Scripts
Get-LockEscalationStats: Tables With the Most Lock Escalations
- Tested on: SQL Server 2025 (RTM CU8) 17.0.4075.5, Windows lab instance
- Last verified: 2026-10-24 (all 3 scripts run, Get-BlockingChainsWithPlan against a live block of 2 readers behind an idle head blocker)
- Permissions: VIEW SERVER STATE for all 3. Get-LockEscalationStats also needs VIEW DATABASE STATE in every database you want counted, otherwise that database is simply absent from the result rather than raising an error
- Safety: read-only, impact low. Get-BlockingChainsWithPlan creates and drops one temp table (
#ar) in your own session
/*
Script Name : Get-LockEscalationStats
Category    : performance
Purpose     : Shows tables with the most lock escalations since last restart.
              Lock escalation converts row/page locks to a table lock, increasing blocking.
Author      : Peter Whyte (https://sqldba.blog/dba-scripts-get-lock-contention-and-blocking-plans/)
Requires    : VIEW SERVER STATE
*/
-- SAFE:ReadOnly
-- IMPACT:Low
SET NOCOUNT ON;
SET QUOTED_IDENTIFIER ON;

/*
  DESIGN: sys.dm_db_index_operational_stats with NULL parameters covers all databases
  and all indexes. Aggregated per table (summing across all indexes) since escalation
  is a table-level event. Excludes system databases (database_id <= 4).

  High escalation counts on a table indicate:
    - Large batch operations scanning many rows (e.g. bulk updates, large deletes)
    - Queries that acquire more than 5,000 row/page locks in a single statement
  Remedies:
    - ALTER TABLE t SET (LOCK_ESCALATION = DISABLE), prevents escalation (use carefully)
    - Batch large DML into smaller chunks to stay below the lock threshold
    - Add covering indexes to reduce rows scanned per operation
    - Use READ_COMMITTED_SNAPSHOT isolation to eliminate shared locks on reads
*/

SELECT TOP 30
    DB_NAME(ios.database_id) AS database_name,
    OBJECT_NAME(ios.object_id, ios.database_id) AS table_name,
    SUM(ios.index_lock_promotion_count) AS lock_escalations,
    SUM(ios.row_lock_count) AS row_lock_count,
    SUM(ios.page_lock_count) AS page_lock_count,
    SUM(ios.row_lock_wait_count) AS row_lock_wait_count,
    SUM(ios.page_lock_wait_count) AS page_lock_wait_count,
    CAST(SUM(ios.row_lock_wait_in_ms) / 1000.0 AS decimal(12,2)) AS row_lock_wait_sec,
    CAST(SUM(ios.page_lock_wait_in_ms) / 1000.0 AS decimal(12,2)) AS page_lock_wait_sec
FROM sys.dm_db_index_operational_stats(NULL, NULL, NULL, NULL) ios
WHERE ios.database_id > 4
  AND ios.index_lock_promotion_count > 0
GROUP BY
    ios.database_id,
    ios.object_id
ORDER BY
    lock_escalations DESC;
Get-ContentionAnalysis: Lock, Latch, Page Latch and Spinlock Contention in One Pass
/*
Script Name : Get-ContentionAnalysis
Category    : performance
Purpose     : Unified contention summary across lock waits, latch waits, page latch
              (allocation) waits, and spinlock contention. All figures are cumulative
              since the last SQL Server restart, so high counts on a recently restarted
              instance are not necessarily concerning.
              sys.dm_os_wait_stats carries no database column, so the PAGE_LATCH rows
              are not attributed to a database. Confirm which database and page with
              sys.dm_os_waiting_tasks.resource_description while the wait is happening.
Author      : Peter Whyte (https://sqldba.blog/dba-scripts-get-lock-contention-and-blocking-plans/)
Requires    : VIEW SERVER STATE
*/
-- SAFE:ReadOnly
-- IMPACT:Low
SET NOCOUNT ON;
SET QUOTED_IDENTIFIER ON;

DECLARE @min_wait_count BIGINT = 100; -- suppress trivial entries with fewer wait occurrences
DECLARE @min_spinlock_collisions BIGINT = 50000; -- only flag high-volume spinlocks

SELECT
    contention_type,
    resource_name,
    wait_count,
    total_wait_ms,
    avg_wait_ms,
    days_since_restart,
    note
FROM (

    -- ── Lock waits ──────────────────────────────────────────────────────────────
    -- LCK_M_* waits represent time spent waiting for row/page/object locks.
    -- High values combined with active blocking indicate a locking hotspot.
    SELECT
        'LOCK' AS contention_type,
        ws.wait_type AS resource_name,
        ws.waiting_tasks_count AS wait_count,
        ws.wait_time_ms AS total_wait_ms,
        CAST(ws.wait_time_ms * 1.0
             / NULLIF(ws.waiting_tasks_count, 0) AS DECIMAL(12,2)) AS avg_wait_ms,
        uptime.days_since_restart,
        'Locking contention - run Get-BlockingChains for real-time chain analysis' AS note
    FROM sys.dm_os_wait_stats ws
    CROSS JOIN (
        SELECT DATEDIFF(DAY, sqlserver_start_time, GETDATE()) AS days_since_restart
        FROM sys.dm_os_sys_info
    ) uptime
    WHERE ws.wait_type LIKE 'LCK_M_%'
      AND ws.waiting_tasks_count >= @min_wait_count

    UNION ALL

    -- ── Latch waits ─────────────────────────────────────────────────────────────
    -- Latches protect internal memory structures. PAGEIOLATCH = I/O waits on data pages.
    -- ACCESS_METHODS / BUFFER / FGCB = internal structure contention.
    SELECT
        'LATCH',
        ls.latch_class,
        ls.waiting_requests_count,
        ls.wait_time_ms,
        CAST(ls.wait_time_ms * 1.0
             / NULLIF(ls.waiting_requests_count, 0) AS DECIMAL(12,2)),
        uptime.days_since_restart,
        CASE
            WHEN ls.latch_class LIKE 'PAGEIOLATCH%'
                THEN 'I/O latch - data page reads are slow; check disk latency'
            WHEN ls.latch_class LIKE 'ACCESS_METHODS%'
                THEN 'Scan/seek contention - high concurrent read/write activity'
            WHEN ls.latch_class = 'BUFFER'
                THEN 'Buffer pool contention - memory pressure or heavy page access'
            WHEN ls.latch_class LIKE 'FGCB%'
                THEN 'Filegroup cache contention - check filegroup configuration'
            ELSE 'Internal latch contention - investigate if avg_wait_ms is high'
        END
    FROM sys.dm_os_latch_stats ls
    CROSS JOIN (
        SELECT DATEDIFF(DAY, sqlserver_start_time, GETDATE()) AS days_since_restart
        FROM sys.dm_os_sys_info
    ) uptime
    WHERE ls.waiting_requests_count >= @min_wait_count
      AND ls.latch_class NOT LIKE 'LOG_%' -- log latches are usually expected
      AND ls.latch_class NOT LIKE 'LOGGING_%'

    UNION ALL

    -- ── TempDB allocation page contention ────────────────────────────────────────
    -- PAGELATCH_UP/EX on TempDB is classic allocation bitmap contention (PFS, GAM, SGAM).
    -- Symptom: many concurrent object creates/drops in TempDB (temp tables, table variables).
    -- Fix (TempDB only): add TempDB data files up to the number of logical CPUs (max 8).
    -- IMPORTANT: sys.dm_os_wait_stats returns 5 columns and none of them is a database,
    -- so these rows are instance-wide. PAGELATCH_* on a user database is ordinary page
    -- contention, not allocation-bitmap contention, and adding TempDB files will not
    -- help it. Confirm the database before acting: while the wait is live, read
    -- sys.dm_os_waiting_tasks.resource_description, which reads <db_id>:<file_id>:<page_id>
    -- (TempDB is database_id 2), and treat page ids 1, 2 and 3 as PFS, GAM and SGAM.
    SELECT
        'PAGE_LATCH',
        ws.wait_type,
        ws.waiting_tasks_count,
        ws.wait_time_ms,
        CAST(ws.wait_time_ms * 1.0
             / NULLIF(ws.waiting_tasks_count, 0) AS DECIMAL(12,2)),
        uptime.days_since_restart,
        CASE ws.wait_type
            WHEN 'PAGELATCH_UP' THEN 'Update page latch, the PFS/GAM/SGAM shape. Confirm the database in sys.dm_os_waiting_tasks before adding TempDB files'
            WHEN 'PAGELATCH_EX' THEN 'Exclusive page latch. Allocation bitmap contention if the pages are TempDB 2:1:1/2:1:2/2:1:3, otherwise ordinary page contention'
            ELSE 'Shared page latch, allocation page reads. Check the database in sys.dm_os_waiting_tasks'
        END
    FROM sys.dm_os_wait_stats ws
    CROSS JOIN (
        SELECT DATEDIFF(DAY, sqlserver_start_time, GETDATE()) AS days_since_restart
        FROM sys.dm_os_sys_info
    ) uptime
    WHERE ws.wait_type IN ('PAGELATCH_UP', 'PAGELATCH_EX', 'PAGELATCH_SH')
      AND ws.waiting_tasks_count >= @min_wait_count

    UNION ALL

    -- ── Spinlock contention ──────────────────────────────────────────────────────
    -- Spinlocks are lightweight CPU-spinning locks protecting very short-lived structures.
    -- High spins-per-collision ratio (>1000) on a specific spinlock indicates a hot path.
    -- Note: total_wait_ms = spins / 1000 (proxy, spinlocks do not track wall-clock time).
    -- avg_wait_ms = spins per collision (spin ratio, not milliseconds).
    SELECT
        'SPINLOCK',
        ss.name,
        ss.collisions,
        ss.spins / 1000, -- proxy: not ms, but comparable magnitude for sorting
        CAST(ss.spins * 1.0 / NULLIF(ss.collisions, 0) AS DECIMAL(12,2)), -- spin ratio
        uptime.days_since_restart,
        'Spin ratio: ' + CAST(CAST(ss.spins * 1.0 / NULLIF(ss.collisions, 0) AS DECIMAL(10,0)) AS VARCHAR)
            + ' spins/collision - avg_wait_ms column shows spin ratio, not ms'
    FROM sys.dm_os_spinlock_stats ss
    CROSS JOIN (
        SELECT DATEDIFF(DAY, sqlserver_start_time, GETDATE()) AS days_since_restart
        FROM sys.dm_os_sys_info
    ) uptime
    WHERE ss.collisions >= @min_spinlock_collisions
      AND ss.spins / NULLIF(ss.collisions, 0) > 1000

) contention
ORDER BY
    CASE contention_type
        WHEN 'LOCK' THEN 1
        WHEN 'LATCH' THEN 2
        WHEN 'PAGE_LATCH' THEN 3
        WHEN 'SPINLOCK' THEN 4
    END,
    total_wait_ms DESC;
Get-BlockingChainsWithPlan: Blocking Chains With the Query Plan Attached
/*
Script Name : Get-BlockingChainsWithPlan
Category    : diagnostics
Purpose     : Same as Get-BlockingChains.sql with the addition of query_plan for
              every session that has a cached plan. Use the PowerShell wrapper to
              extract plans to individual XML files. Plan will be NULL for idle
              head blockers (no active request) and sessions still in parse/compile.
Author      : Peter Whyte (https://sqldba.blog/dba-scripts-get-lock-contention-and-blocking-plans/)
Requires    : VIEW SERVER STATE

Performance note: dm_exec_requests is materialised into #ar once to avoid
repeated DMV scans. downstream_waiters is pre-aggregated rather than computed
via a correlated subquery. dm_exec_connections is joined only for sessions
that have no active request (idle head blockers).

query_plan is returned as xml, so in SSMS it is a link that opens the graphical plan.

Reading the output: the head blocker row is the one to act on. query_plan is NULL
on an idle head blocker because a sleeping session has no active request and so no
plan_handle; its sql_text comes from most_recent_sql_handle and is the whole last
batch, not one statement. wait_resource names the locked object for each waiter:
KEY: <db_id>:<hobt_id> (<hash>), PAGE: <db_id>:<file_id>:<page_id>,
OBJECT: <db_id>:<object_id>. Returns no rows when the server is not blocked.
*/
-- SAFE:ReadOnly
-- IMPACT:Low
SET NOCOUNT ON;
SET QUOTED_IDENTIFIER ON;

DROP TABLE IF EXISTS #ar;

SELECT
    session_id, blocking_session_id, status, wait_type, wait_resource, wait_time,
    cpu_time, logical_reads, writes, total_elapsed_time,
    sql_handle, plan_handle, database_id,
    statement_start_offset, statement_end_offset
INTO #ar
FROM sys.dm_exec_requests
WHERE session_id <> @@SPID;

WITH
DownstreamCounts AS (
    SELECT blocking_session_id,
           COUNT(*) AS downstream_waiters
    FROM #ar
    WHERE blocking_session_id > 0
    GROUP BY blocking_session_id
),
Chain AS (
    -- Anchor: head blockers, they block others but are not themselves blocked
    SELECT
        s.session_id AS chain_id,
        0 AS chain_level,
        CAST('head blocker' AS VARCHAR(16)) AS role,
        CAST(0 AS SMALLINT) AS blocker_session_id,
        s.session_id,
        s.login_name,
        s.host_name,
        s.program_name,
        s.open_transaction_count,
        COALESCE(r.status, s.status) AS status,
        r.wait_type,
        r.wait_resource,
        r.wait_time,
        r.cpu_time,
        r.logical_reads,
        r.writes,
        r.total_elapsed_time,
        COALESCE(r.database_id, s.database_id) AS database_id,
        COALESCE(r.statement_start_offset, 0) AS statement_start_offset,
        COALESCE(r.statement_end_offset, -1) AS statement_end_offset,
        COALESCE(r.sql_handle, c.most_recent_sql_handle) AS sql_handle,
        r.plan_handle
    FROM sys.dm_exec_sessions AS s
    LEFT JOIN #ar AS r ON r.session_id = s.session_id
    LEFT JOIN sys.dm_exec_connections AS c ON c.session_id = s.session_id
                                          AND r.session_id IS NULL
    WHERE s.is_user_process = 1
      AND EXISTS (SELECT 1 FROM #ar WHERE blocking_session_id = s.session_id)
      AND NOT EXISTS (SELECT 1 FROM #ar WHERE session_id = s.session_id AND blocking_session_id > 0)

    UNION ALL

    -- Recursive: victims blocked by the previous chain level
    SELECT
        ch.chain_id,
        ch.chain_level + 1,
        CAST('blocked' AS VARCHAR(16)),
        r.blocking_session_id,
        r.session_id,
        s.login_name,
        s.host_name,
        s.program_name,
        s.open_transaction_count,
        r.status,
        r.wait_type,
        r.wait_resource,
        r.wait_time,
        r.cpu_time,
        r.logical_reads,
        r.writes,
        r.total_elapsed_time,
        r.database_id,
        r.statement_start_offset,
        r.statement_end_offset,
        r.sql_handle,
        r.plan_handle
    FROM #ar AS r
    JOIN sys.dm_exec_sessions AS s ON s.session_id = r.session_id
    JOIN Chain AS ch ON ch.session_id = r.blocking_session_id
    WHERE r.blocking_session_id > 0
)
SELECT
    ch.chain_id,
    ch.chain_level,
    ch.role,
    ch.blocker_session_id,
    ch.session_id,
    ch.login_name,
    ch.host_name,
    ch.program_name,
    DB_NAME(ch.database_id) AS database_name,
    ch.open_transaction_count,
    ch.status,
    ch.wait_type,
    ch.wait_resource,
    ISNULL(ch.wait_time, 0) AS wait_time_ms,
    ISNULL(ch.cpu_time, 0) AS cpu_time_ms,
    ISNULL(ch.logical_reads, 0) AS logical_reads,
    ISNULL(ch.writes, 0) AS writes,
    ISNULL(ch.total_elapsed_time, 0) AS total_elapsed_time_ms,
    ISNULL(dc.downstream_waiters, 0) AS downstream_waiters,
    CAST(
        (ISNULL(su.user_objects_alloc_page_count, 0) +
         ISNULL(su.internal_objects_alloc_page_count, 0)) * 8
    AS BIGINT) AS tempdb_allocations_kb,
    CAST(
        (ISNULL(su.user_objects_alloc_page_count, 0) - ISNULL(su.user_objects_dealloc_page_count, 0) +
         ISNULL(su.internal_objects_alloc_page_count, 0) - ISNULL(su.internal_objects_dealloc_page_count, 0)) * 8
    AS BIGINT) AS tempdb_current_kb,
    SUBSTRING(
        ISNULL(qt.text, ''),
        (ch.statement_start_offset / 2) + 1,
        CASE
            WHEN ch.statement_end_offset = -1
                THEN LEN(ISNULL(qt.text, ''))
            ELSE (ch.statement_end_offset - ch.statement_start_offset) / 2 + 1
        END
    ) AS sql_text,
    qp.query_plan AS query_plan
FROM Chain AS ch
LEFT JOIN DownstreamCounts AS dc ON dc.blocking_session_id = ch.session_id
LEFT JOIN sys.dm_db_session_space_usage AS su ON su.session_id = ch.session_id
OUTER APPLY sys.dm_exec_sql_text(ch.sql_handle) AS qt
OUTER APPLY sys.dm_exec_query_plan(
    CASE WHEN ch.plan_handle <> 0x0000000000000000000000000000000000000000
         THEN ch.plan_handle END
) AS qp
ORDER BY
    ch.chain_id,
    ch.chain_level,
    ch.session_id
OPTION (MAXRECURSION 10);
How To Run From The Repo
Clone DBA Tools, initialize and run whichever script answers your question:
# Clone dba-tools repo:
git clone https://github.com/peterwhyte-lgtm/dba-tools

# Initialize environment:
cd dba-tools
.\Initialize-Environment.ps1

# Tables with the most lock escalations:
.\run.ps1 Get-LockEscalationStats

# Lock/latch/TempDB/spinlock contention summary since last restart:
.\run.ps1 Get-ContentionAnalysis

# Blocking chains with the query plan attached (use during an active incident):
.\run.ps1 Get-BlockingChainsWithPlan

# Any of these against a remote sql server:
.\run.ps1 Get-ContentionAnalysis -ServerInstance SQLSERVER01
These scripts live in the repo at:
sql/performance/blocking-locking/Get-LockEscalationStats.sqlsql/performance/blocking-locking/Get-ContentionAnalysis.sqlsql/performance/blocking-locking/Get-BlockingChainsWithPlan.sql
Example Output
Get-BlockingChainsWithPlan, Caught During a Live Block
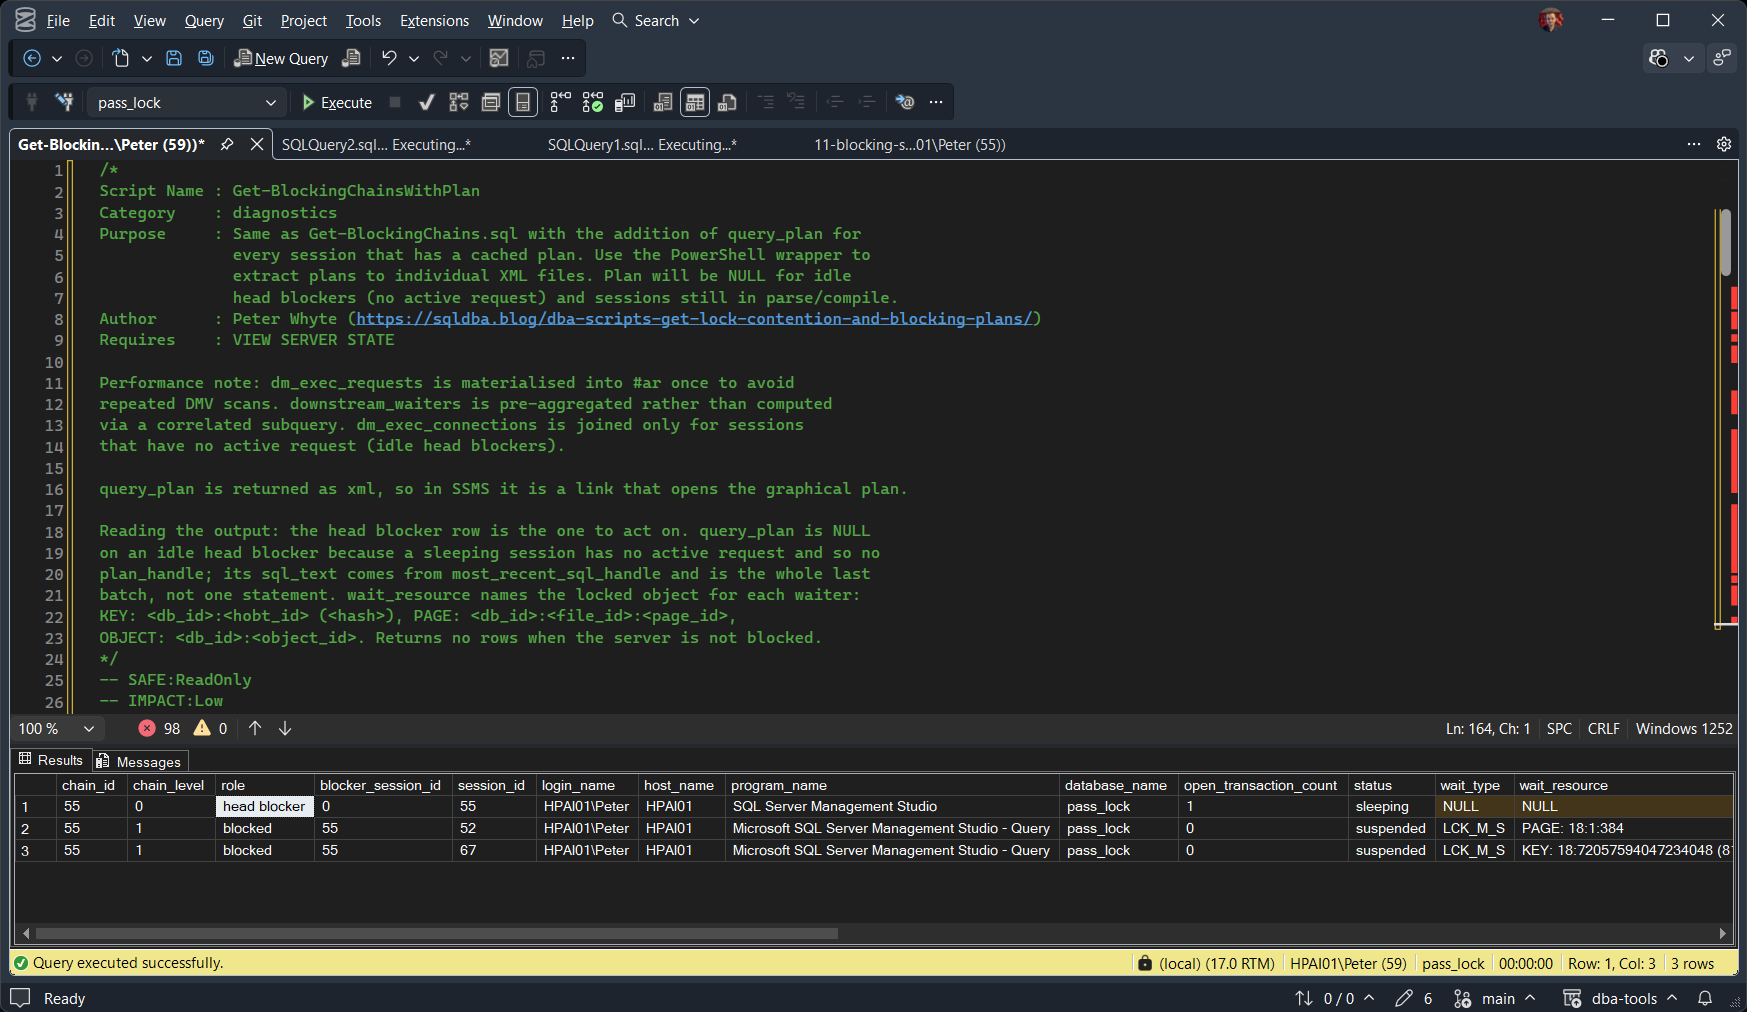
One session opened a transaction, updated a single row, then went idle without committing it. 2 other sessions tried to read that row. This is what the script is for: it names the one session you have to deal with.
Scrolled right, the same grid ends in sql_text and query_plan:
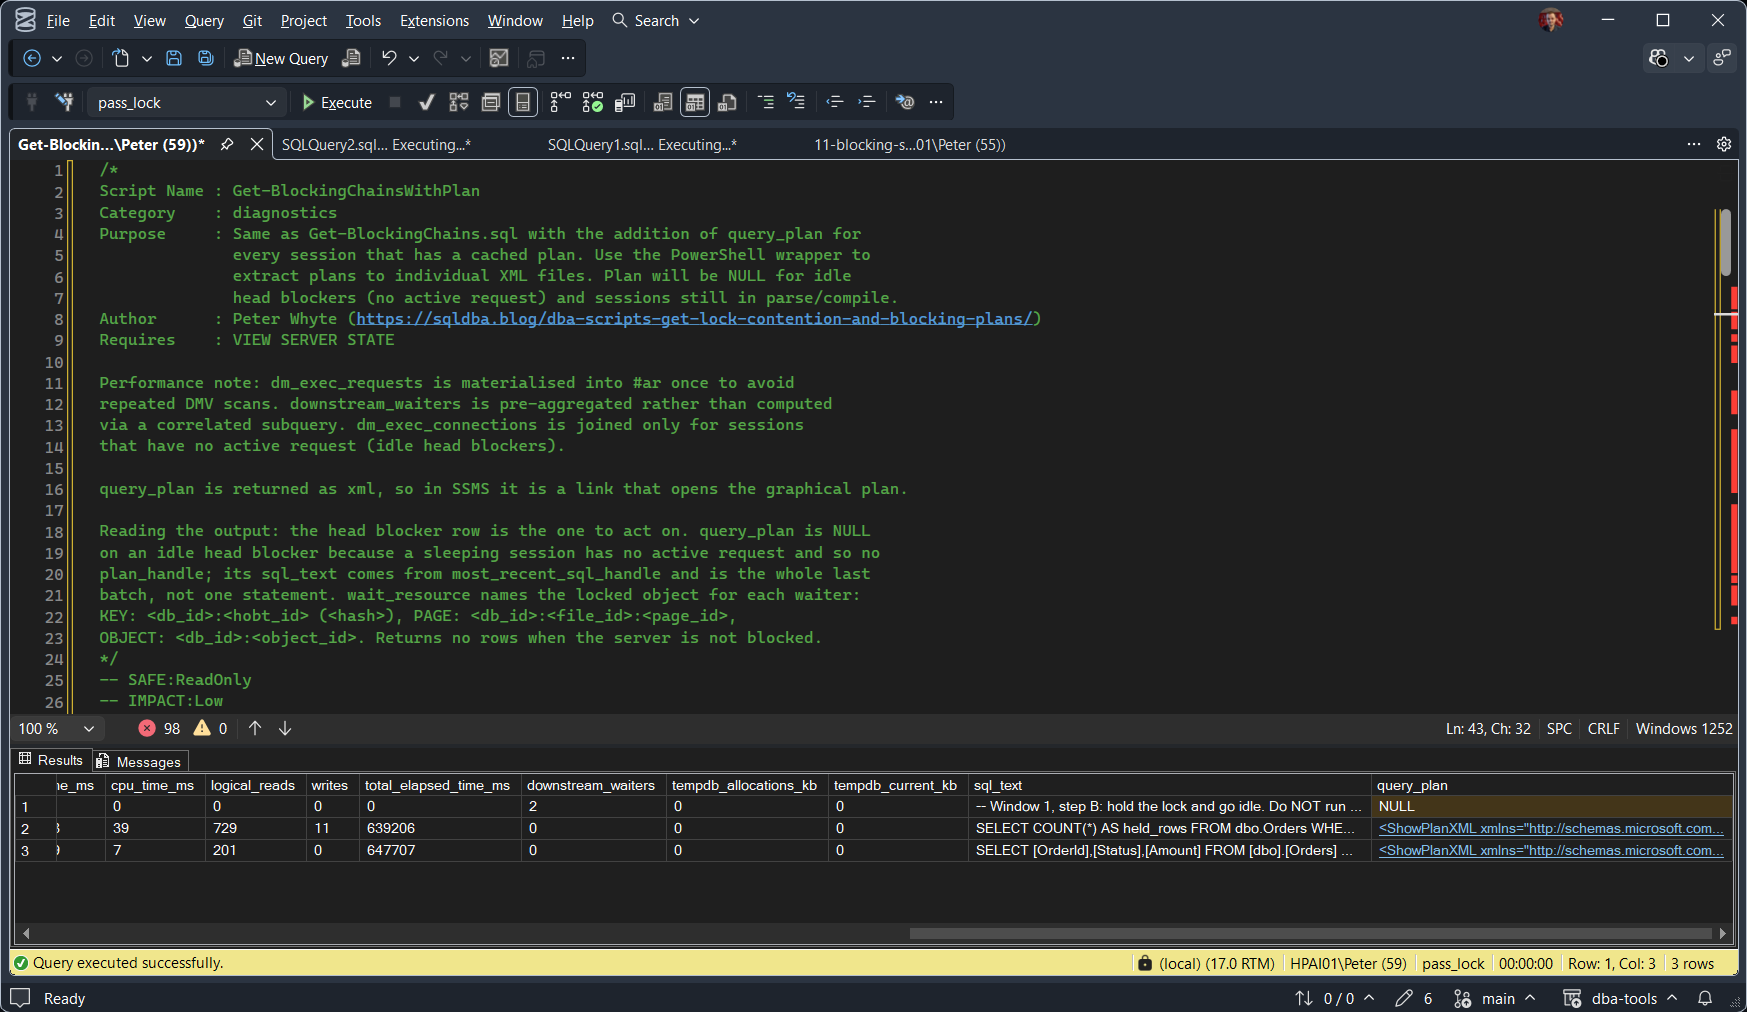
Three things in that grid are worth reading slowly.
roleishead blockeron session 55, and its status issleeping, not running. It holdsopen_transaction_count1 and nothing else. An idle session with an open transaction is the most common blocking cause there is, and no amount of tuning touches it: the transaction has to commit, roll back, or the session has to be killedquery_plancame back NULL on that row and populated on both blocked rows, 4,523 and 3,547 characters of ShowPlanXML built by 17.0.4075.5. In SSMS each one is a link: click it and the graphical plan opens, which is where you see the scan that widened the lockwait_resourcenames the object, which is what tells you where to look.KEY: 18:72057594047234048resolves to the primary key ofOrdersin database_id 18, found withSELECT OBJECT_NAME(object_id) FROM sys.partitions WHERE hobt_id = 72057594047234048run inside that database.PAGE: 18:1:384is database_id 18, file 1, page 384
Get-ContentionAnalysis, Cumulative Since the Last Restart
Thirteen rows against 3 days of uptime. The note column is cut from the capture for width; on the real grid it repeats in plain English what each row means.
The LCK_M_S average of 11,943 ms is not a server problem. It is the block from the section above, still being held while this ran. That is worth knowing, because it is the shape a real incident leaves in cumulative statistics: a small wait_count with an enormous average. The opposite shape, a large count with a tiny average like the 36,906 LCK_M_SCH_M waits at 1.60 ms each, is ordinary schema-stability traffic and not worth chasing. The lock waits library entry has the per-wait meanings.
Get-LockEscalationStats, After One 20,000 Row Update
A single UPDATE over 20,000 rows in one statement crosses the escalation threshold, which the MS Docs locking and row versioning guide puts at roughly 5,000 locks taken on one table in one statement. Checking sys.dm_tran_locks for that session inside the transaction afterwards returns 1 OBJECT lock in X mode and nothing finer, where a sub-threshold update would still be holding thousands of row locks. That is escalation, and the script counts it.
One escalation, and the 225 seconds of row_lock_wait_sec on the same row is what the 2 blocked readers paid for it. On an instance where nothing has crossed the threshold the script returns no rows at all, which is the answer you want rather than a failure.
Understanding the Results
rolechain_levelchain_level 0 first. That row is the head blocker, the session at the top of the chain, and it is the only one worth acting on. Every blocked row underneath it is a symptom. Chains can run deeper than 2 levels, and OPTION (MAXRECURSION 10) caps the recursion at 10, so a longer chain comes back short rather than failing.open_transaction_countstatussleeping with open_transaction_count above 0 is the classic one: an application opened a transaction and went quiet. No query is running, so there is nothing to tune.Act when you see it. The transaction has to end. Find out what the application is doing first, then commit, roll back, or kill the session and accept the rollback. The full order of work is in Troubleshoot SQL Server Blocking.wait_resourceKEY: db_id:hobt_id (hash) resolves through sys.partitions inside that database, PAGE: db_id:file_id:page_id and OBJECT: db_id:object_id read straight off. Without this column you know who is blocked. With it you know what to fix.downstream_waitersquery_planplan_handle to pass to sys.dm_exec_query_plan. Its sql_text comes from most_recent_sql_handle instead, which returns the whole last batch rather than one statement. A plan is also NULL while a statement is still compiling, and for anything already evicted from the plan cache.wait_typeLCK_M_ wait, and the suffix is the lock mode being requested: LCK_M_S shared, LCK_M_X exclusive, LCK_M_U update, LCK_M_SCH_M schema modification, with LCK_M_IX and LCK_M_IS the intent forms taken higher up the hierarchy. The lock waits entry covers each one.contention_type = LOCKavg_wait_ms rather than total_wait_ms, and always against days_since_restart. A large total on a server that has been up for months can mean nothing at all.Act when avg_wait_ms runs into whole seconds. That is a held transaction rather than contention. Cross-reference Blocking Chains or Get-BlockingChainsWithPlan while it is still happening.contention_type = LATCHBUFFER accumulates on every page access on the instance, so it is usually the largest total on the page and usually means nothing. ACCESS_METHODS_DATASET_PARENT is parallel scan coordination. Read avg_wait_ms, not the total: the 5,147,702 BUFFER waits in the capture average 1.91 ms, which is healthy.contention_type = PAGE_LATCHsys.dm_os_wait_stats returns 5 columns and not one of them is a database, so these rows are instance-wide and do not prove TempDB is involved. The PFS, GAM and SGAM pages are pages 1, 2 and 3 of each data file.Act when you have confirmed the database first. While the wait is live, read sys.dm_os_waiting_tasks.resource_description, which reads db_id:file_id:page_id, and check that it says database_id 2. Adding TempDB data files does nothing for page latch waits on a user database, and TempDB Hotspots is the script that attributes them.lock_escalationsrow_lock_wait_count and row_lock_wait_sec on the same row: escalation with no waiting costs nothing, escalation with waiting is the blocking you came here about.Act when the wait columns are non-zero too. Batch the DML below the threshold first, then look at READ_COMMITTED_SNAPSHOT. Leave LOCK_ESCALATION = DISABLE until last: it is what turns blocking into error 1204.Best Practices
- Run
Get-ContentionAnalysisas a routine health check, and readdays_since_restartbefore anything else. The figures are cumulative since restart, so a recently restarted instance shows low numbers whatever is wrong with it - Reach for
Get-BlockingChainsWithPlanduring an active incident, once you already know blocking is happening. Use the lighter Blocking Chains for routine checks, because retrieving a plan per session is work the routine check does not need - Act on the
chain_level0 row and nothing else. Killing a victim frees one session and changes nothing: the head blocker immediately blocks the next one in the queue - Treat any table with real lock escalations as a candidate for query batching or a
READ_COMMITTED_SNAPSHOTreview, not just a data point to note. Escalation with zero wait counts beside it is not costing anything yet - Confirm the database behind a
PAGE_LATCHrow insys.dm_os_waiting_tasksbefore adding TempDB data files. The fix is standard and well tested for TempDB allocation pages, and irrelevant for page latch waits anywhere else - Capture the chain before you kill anything. Once the transaction is gone, so is
wait_resource, the plan and the evidence of what caused it
MS Docs: sys.dm_os_waiting_tasks, the view that names the database and page behind a page latch while it is happening.
Frequently Asked Questions
Why is query_plan empty for the exact session causing the problem?
Because the head blocker is usually asleep. sys.dm_exec_query_plan needs a plan_handle, and a plan_handle only exists for a session with an active request. A session that opened a transaction and went idle has no request, so there is nothing to look up. The script falls back to most_recent_sql_handle for the text, which returns the whole last batch rather than one statement, so you still see what it ran. The plans you do get are for the blocked sessions, which is the opposite of what you want but still tells you what is queueing up.
If you need the blocker own plan, catch it while it is running. NULL here is not a bug and not a permissions problem.
The output says PAGE_LATCH. Should I add TempDB files?
Not on this evidence. sys.dm_os_wait_stats returns 5 columns, wait_type, waiting_tasks_count, wait_time_ms, max_wait_time_ms and signal_wait_time_ms, and none of them is a database. A PAGELATCH_UP total is instance-wide, so it cannot tell you whether the contention is on TempDB allocation bitmaps or on a hot page in a user table. Adding TempDB data files fixes the first and does nothing for the second.
Confirm first. While the wait is live, read resource_description in sys.dm_os_waiting_tasks: it reads db_id:file_id:page_id, TempDB is database_id 2, and pages 1, 2 and 3 of each file are PFS, GAM and SGAM. Allocation contention means repeated hits on those low page numbers in database 2.
What does a wait_resource like KEY: 18:72057594047234048 point at?
The first number is the database_id and the second is the hobt_id, the heap or B-tree the lock is on. Resolve it from inside that database with SELECT OBJECT_NAME(p.object_id), i.name FROM sys.partitions p JOIN sys.indexes i ON i.object_id = p.object_id AND i.index_id = p.index_id WHERE p.hobt_id = 72057594047234048. The trailing value in brackets is a hash of the key itself, which identifies the row but does not decode back into column values.
The other 2 shapes are simpler. PAGE: db_id:file_id:page_id is a page, and OBJECT: db_id:object_id is a whole table, which is what you see after lock escalation.
Why is total_wait_ms so much higher for LATCH than for LOCK?
Latch waits, and BUFFER in particular, accumulate on every page access on the instance. That is a far higher-frequency event than a lock wait, which only happens under genuine contention. A large LATCH total is normal and not automatically a problem.
Compare avg_wait_ms instead, and read it against days_since_restart. Millions of BUFFER waits averaging under 2 ms is a healthy instance. A few hundred lock waits averaging several seconds is one held transaction, and that is the one to chase.
Get-LockEscalationStats returns no rows. Does that mean escalation cannot happen here?
No. It means no table has crossed the threshold, roughly 5,000 locks in one statement, since the last restart. The counters live in sys.dm_db_index_operational_stats, which is memory-resident and cleared on restart, and the rows for an object can be dropped from the cache before that. A large batch job tomorrow can produce an escalation on a table that reads clean today.
One more reason for a missing database: the script calls the function with NULL parameters, which needs VIEW DATABASE STATE in each database. Where you do not have it the database is quietly absent from the result rather than raising an error.
Summary
Blocking and contention surface in different DMVs depending on what is actually causing them: lock escalation converting row locks into one table lock, cumulative wait statistics across 4 resource types, or a live chain with the query behind it. These 3 scripts cover that range, from has this ever been a problem to which session do I deal with right now.
In an incident, run Get-BlockingChainsWithPlan, read the chain_level 0 row, and use wait_resource to find the object. Keep Get-ContentionAnalysis and Get-LockEscalationStats for the question afterwards, which is whether it was a one-off or something the workload does every week.
Related
You may also find these useful:
- Blocking and Locking (hub)
- Blocking Chains
- Blocking Sessions
- Deadlock Summary
- Temp DB Hotspots
- Open Transactions, the script that finds the idle head blocker before it blocks anyone
- Troubleshoot SQL Server Blocking, Step by Step
- How To Kill a SPID in SQL Server, and what the rollback costs you
- Lock Waits (LCK_M_*), the wait library entry behind every blocked row
- DBA Scripts: The Complete Guide, the map across every script on this site
Leave a Reply