
Inherited a server, or sure something is wrong but not what? One command runs 45 read-only checks against the instance. A second turns the results into a ranked CRITICAL / WARNING / INFO list. An optional third hands the lot to an AI to find the root causes.
Step 1: Collect
git clone https://github.com/peterwhyte-lgtm/dba-tools
cd dba-tools
.\Initialize-Environment.ps1

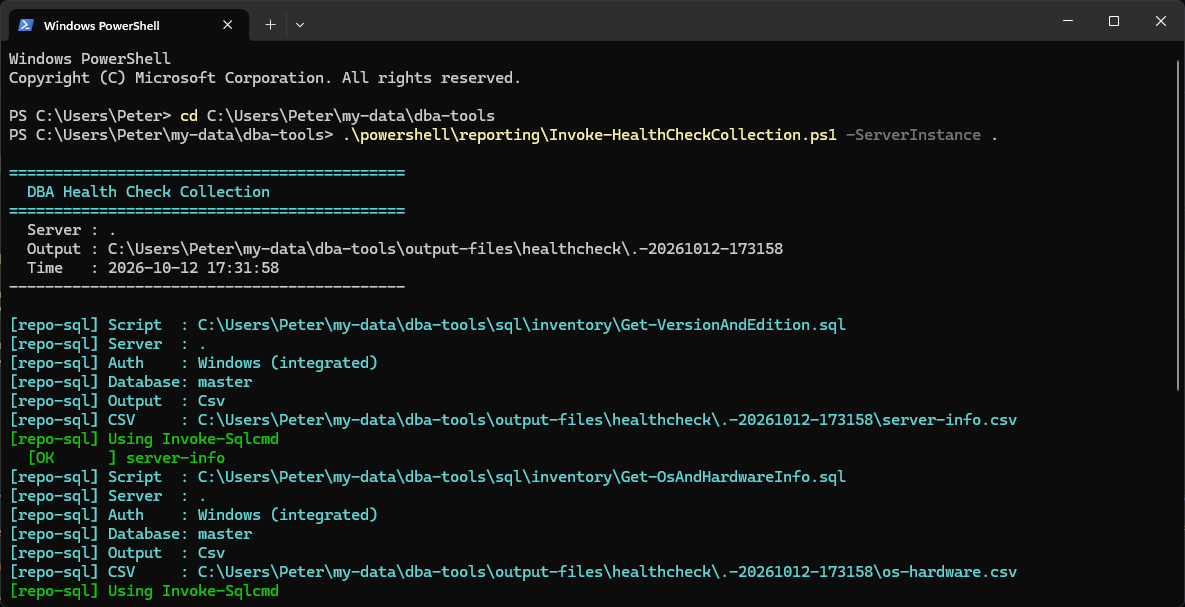
.\powershell\reporting\Invoke-HealthCheckCollection.ps1 -ServerInstance . -Quiet
This runs 45 scripts against the instance, one per area: inventory, backups, waits, security, TempDB, indexes, Agent jobs, and High Availability (Always On replica state, failover readiness and latency, mirroring endpoints, replication, FCI node blips). Each result is saved as a CSV in a timestamped folder under output-files\healthcheck\.
All 45 scripts carry a SAFE:ReadOnly header, so nothing in the collection changes the instance. Leave off -Quiet to see each script’s path and connection details as it runs. Run it as sysadmin.
VIEW SERVER STATE, VIEW ANY DATABASE and VIEW ANY DEFINITION: 8 fail. 3 read the Agent job tables in msdb, 3 call
xp_readerrorlog, plus autogrowth history (the default trace) and database sizes (a database the login cannot open).CONNECT SQL only: 23 fail.
A failed script shows
[FAILED] with the error under it, and the run carries on.All 45 ran clean. 3 came back empty: suspect pages, CDC and Change Tracking, and orphaned users. That is not a failure. The check ran, found nothing and wrote an empty CSV.
The High Availability scripts write a status row instead, such as “Always On Availability Groups is not enabled or no groups are configured on this instance.” That way the assessment reports those areas as checked, not skipped.
Step 2: Review
.\powershell\reporting\Review-HealthCheckOutput.ps1
This reads every CSV from the most recent collection, applies fixed threshold rules and gives you a ranked findings list: CRITICAL, WARNING, INFO. 35 of the 45 CSVs have rules. They look for:
- Backups: no full backup, or one older than 24 hours (CRITICAL). In FULL or BULK_LOGGED recovery, no log backup or one older than 4 hours.
- Integrity:
DBCC CHECKDBolder than 7 days, or older than 14 days or never run (CRITICAL). Any suspect pages (CRITICAL). - Database settings: databases not ONLINE (CRITICAL), auto-shrink, auto-close and percent-based autogrowth.
- Space: a log over 80% used, data files under 10% free, databases at or near their growth limit, volumes under 10% free (under 5% is CRITICAL), and VLF counts over 50, 200 and 1000 (INFO, WARNING, CRITICAL).
- Performance: read or write latency over 50 ms, PAGEIOLATCH, WRITELOG, RESOURCE_SEMAPHORE, CXPACKET, CXCONSUMER, LCK_M_X or ASYNC_NETWORK_IO over 10% of total wait time, max server memory left at the default, TempDB file count, sizing and autogrowth, and a plan cache full of single-use plans. Blocking and open transactions are INFO.
- Agent jobs: any job failure in the last 7 days, no
DBA - Backup - FULLjob, and maintenance jobs that failed or are disabled. - Security: sa enabled (CRITICAL) and other weak login settings, locked-out logins and repeated failed logins, xp_cmdshell enabled, risky linked server logins, orphaned users, and expired or expiring certificates.
- Error log: corruption and crash patterns (823, 824, 825, 832, stack dumps) are CRITICAL. Memory pressure (paged out, error 802 or 701) is a WARNING.
- High Availability and features: AG replicas not healthy or disconnected, failover readiness, endpoints not STARTED, inactive replication subscriptions, cluster failover entries in the last 7 days, Query Store switched to READ_ONLY, and CDC, Change Tracking or Service Broker warnings. User Extended Events sessions are INFO.
The other 10 never raise a finding on their own: server and OS inventory, backup coverage, TempDB usage, missing indexes, sysadmin members, instance configuration, top CPU queries, the Agent job overview and autogrowth history. They are context for step 3.
From the same collection, excerpted:
In the console the same review is colour-coded by severity, CRITICAL in red, WARNING in yellow and INFO in cyan:
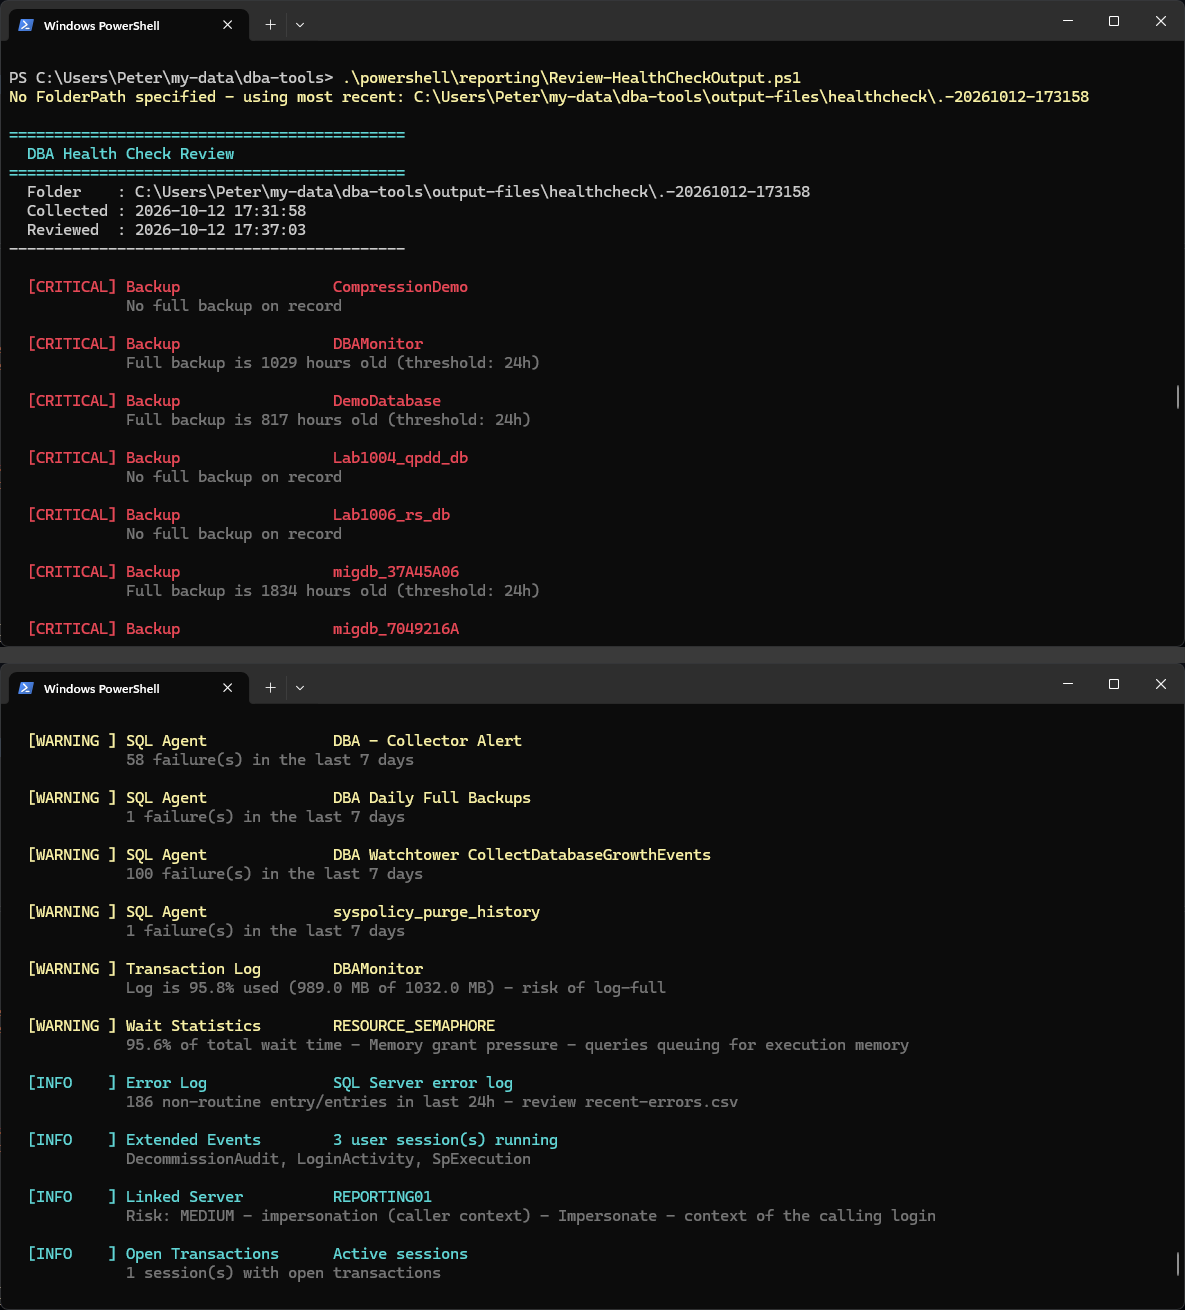
That is what a rules-based health check gives you: a real list, with findings.csv written next to the raw CSVs for tracking over time. But 116 flat findings still leave the real DBA work undone. Which of these are one problem wearing several hats, and which do you fix first?
Step 3: AI Assessment
This is the step that makes the other two worth automating. The same CSVs, plus findings.csv, go to an AI that follows a fixed rubric (powershell/reporting/ai-assessment-rubric.md). Its job is what the rules can’t do: connect signals across files, find root causes, judge severity in context, and write a prioritised report you can act on.
The AI step is optional. Steps 1 and 2 are plain PowerShell and T-SQL, need no API key and no internet access, and still give you the ranked findings list. In a locked-down environment, stop after step 2.
.\powershell\reporting\Invoke-AiAssessment.ps1
It needs ANTHROPIC_API_KEY set, and the report lands in output-files\assessments\. -DryRun writes the exact prompt to the same folder without calling the API. For the collection above that was 47 CSVs and roughly 47,600 tokens. Inside Claude Code, the assessment runs directly against the same CSVs and rubric, with no API call.
From an assessment of an earlier collection on the same lab instance:
That’s the difference in one paragraph. The rules gave separate findings for 7 failing Agent jobs, a memory-pressure pattern in the error log, and a plan cache full of single-use plans. The assessment read the same evidence and found one problem.
The buffer pool is too small for the host, so Windows pages SQL Server out. The plan cache gets flushed, which is why top-cpu-queries.csv came back empty. Collector steps die with error 802, and the top waits are what a starved buffer pool produces.
Evidence: max server memory 1,600 MB against 7.78 GB physical (memory-config.csv); SQL committed only ~227 MB with 68 MB in use; error log shows 11 entries in 24h of “significant part of SQL Server process memory has been paged out” … plus collector job steps failing with error 802 “insufficient memory available in the buffer pool”;
dm_exec_query_stats is empty (0 rows, 6 cached plans), the plan cache is being flushed continuously; top waits after filtering are PAGEIOLATCH_SH 53.7%, RESOURCE_SEMAPHORE 9.8% (avg 9.2 s), THREADPOOL 9.1%.Impact: collectors fail, query performance data is unusable (top-cpu-queries.csv is empty because nothing survives in cache), and any test run on this box measures paging, not SQL Server.
Fix: decide the box’s memory budget. If SQL matters here, raise max server memory to 3 to 4 GB and set min server memory to match (
sp_configure), or accept the squeeze and stop the collectors.The full report also split those 7 failing jobs. Most were dying from the memory pressure (4 logged error 802). The deadlock collector had never succeeded, for a different reason: Agent runs T-SQL job steps with QUOTED_IDENTIFIER OFF and the step uses XML methods, so it failed with error 1934 on every run. Same “Last run FAILED” line in the review, two unrelated root causes. A threshold rule cannot make that split.
Why the Steps Are Separate
- Collection and review can run unattended, on a schedule. A daily collect and review means the findings are already waiting when an incident starts.
- Review is deterministic. The same data gives the same findings every time, so you can track whether an issue count is going up or down over weeks.
- Assessment is where judgement happens. It costs more to run and differs every time, so run it when someone is going to read it and act, not every 15 minutes alongside the collectors.
Reading the Assessment
- Read the Verdict first. It is one paragraph that answers “do I need to act today”. Everything below it is supporting detail.
- Priority Issues are already correlated. If several CRITICAL rows are grouped into one issue, that grouping is the finding. Don’t split them back into separate tickets without a reason.
- Watch List items are not problems yet. Each one says what threshold would make it one. Look again on the next run.
- Checked and Clean matters as much as the findings. It tells you an area was checked and found fine, not just that nothing came up.
Adjusting the Thresholds
The review thresholds assume daily backups and typical SLAs. To change them, edit powershell\reporting\Review-HealthCheckOutput.ps1 directly. Full-backup age, log-backup age, I/O latency and DBCC CHECKDB staleness are all plain conditionals in the script, not a config file to learn.
Running Against a Remote Server
.\powershell\reporting\Invoke-HealthCheckCollection.ps1 -ServerInstance PROD01\SQL2019
.\powershell\reporting\Review-HealthCheckOutput.ps1
.\powershell\reporting\Invoke-AiAssessment.ps1
Each server’s collection lands in its own timestamped folder (PROD01-SQL2019-<timestamp>). The review and the AI step read the most recent folder unless you pass -FolderPath, so run them straight after each collection or point them at the folder. For several instances at once, Invoke-MultiServerHealthCheck.ps1 -Servers "SVR01,SVR02,SVR03" runs the collection and the review against each one and writes a combined findings CSV.
This workflow has dba-tools gather the evidence and an AI correlate it. The sqldba MCP server is the same idea pointed the other way: the assistant asks this site, rather than answering from memory, whenever it needs an error, a wait type, a patch level or a script.
Frequently Asked Questions
What permissions does the health check need?
sysadmin. A monitoring login with VIEW SERVER STATE, VIEW ANY DATABASE and VIEW ANY DEFINITION still fails 8 of the 45 scripts: the Agent job tables in msdb need db_datareader there, xp_readerrorlog needs sysadmin in practice, the default trace needs ALTER TRACE, and database sizes opens every database. MS Docs lists the server permissions if you want to build a narrower login and accept gaps.
Does it change anything on the server?
No. All 45 collection scripts are marked SAFE:ReadOnly, and the only files written are the CSVs on the machine running the command. The review and the AI step read those CSVs and never connect to SQL Server.
Why are some of the CSV files empty?
The check ran and found nothing. On the lab run, suspect pages, CDC and Change Tracking, and orphaned users came back empty, which is the healthy answer for all 3. A script that errored shows [FAILED] in the console instead.
How do I run it on a schedule?
The repo ships no scheduler. Any job that can run PowerShell 7 can call pwsh -NoProfile -File .\powershell\reporting\Invoke-HealthCheckCollection.ps1 -ServerInstance PROD01 -Quiet followed by Review-HealthCheckOutput.ps1, which picks up the newest folder. Run the AI step by hand, when someone is going to read it.
Does the AI step send my data anywhere?
Through the API script, yes: CSV contents, including server, database and login names and file paths, go to the Anthropic API. Run -DryRun first and the exact prompt is written to output-files\assessments\ for review before anything leaves the machine. Collect and review never leave it.
Summary
Collection and review turn “is this server okay” into a ranked list, with no DMV queries typed by hand. The assessment turns that list into what a rules engine can’t produce: root causes across files, severity in context, and a next action for each priority issue. Run collection and review on a schedule. Run the assessment when someone is going to read it.
Related
This workflow’s collection touches nearly every pillar on the site; a few of the most directly related:
- SET Options Have Incorrect Settings (Error 1934), the Agent QUOTED_IDENTIFIER failure described above, worked through in full
- The First Hour on a SQL Server You Have Never Seen, what to ask before you run anything at all
- Get Backup Coverage, the detailed drill-down behind the Backup findings above
- Get Last DBCC CHECKDB, the standalone version of the integrity-check finding
- Cumulative Wait Stats Lie: Measuring Waits Over an Interval
- Silent Failures, the problems a health check exists to catch, because nothing raises an error
- Collectors and Baseline Infrastructure (pillar), the standing jobs behind several of the findings this workflow surfaces
- Backups and Recovery (pillar)
- Security (pillar)
- DBA Scripts: The Complete Guide, the full pillar index
Leave a Reply